The problem
Stated as scale
Volume isn't the hard part. Every name in this package is a proper noun that has to be right. Accents, diacritics, characters that aren't on a US keyboard, capitalization that breaks the rules on purpose.
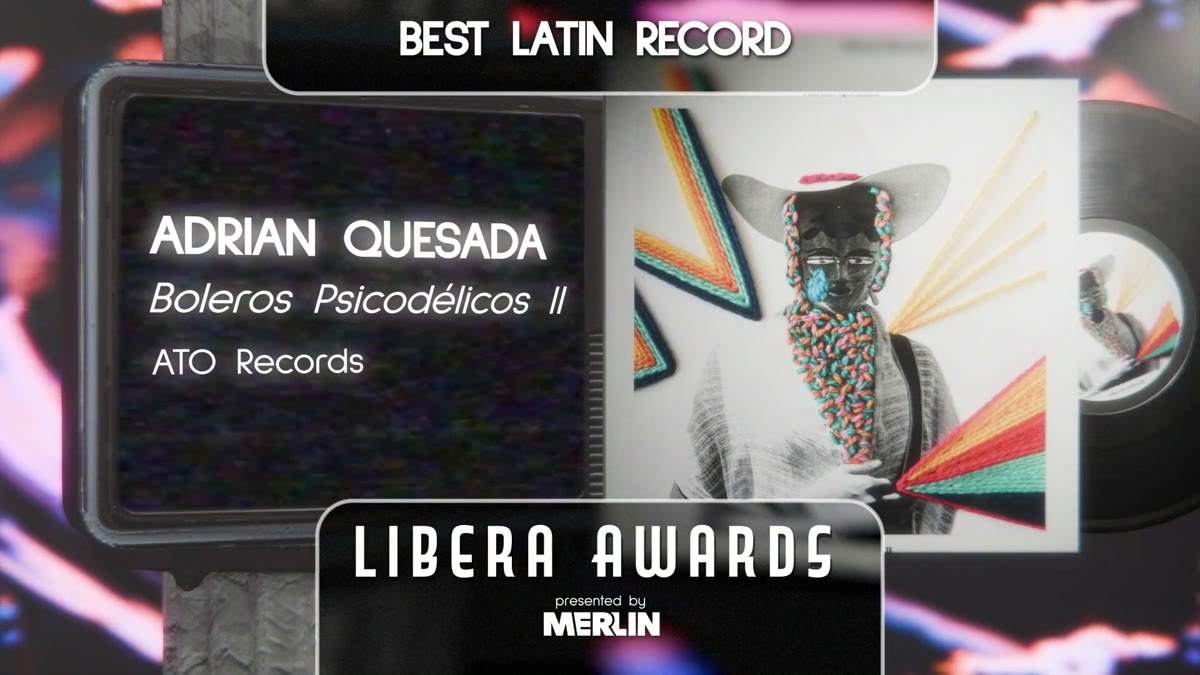
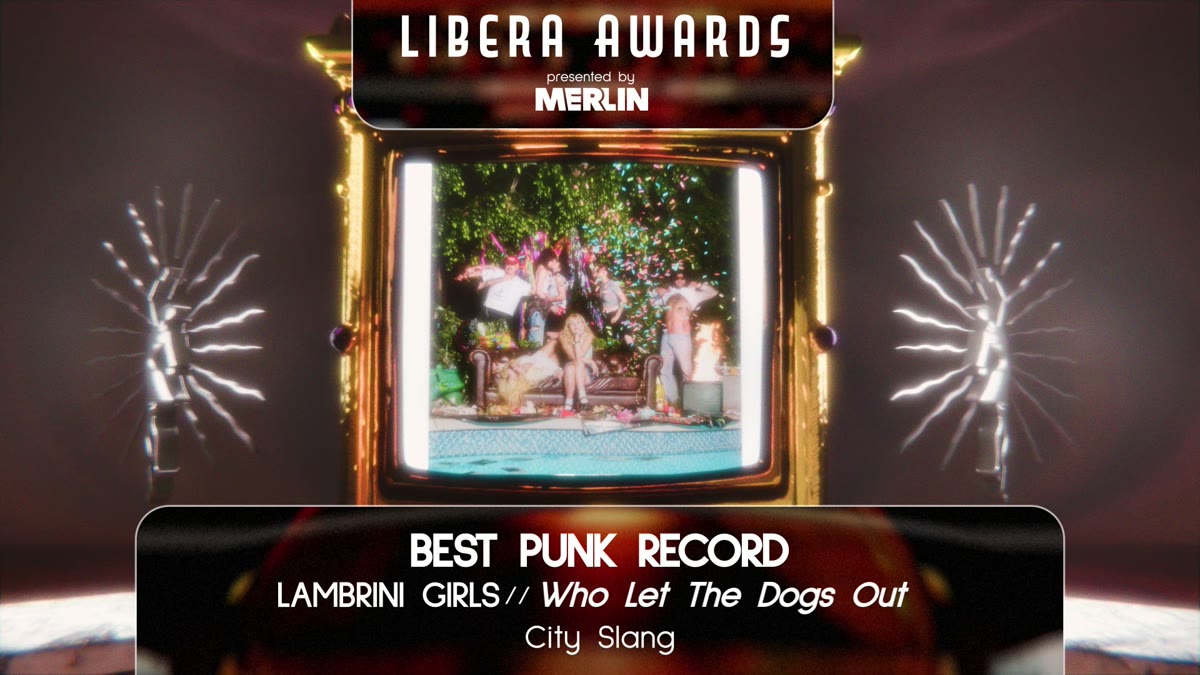
The Libera Awards are the independent music industry's annual awards, produced by the Foundation for Independent Music. I've made the animation package since 2021. Every nominee gets a screen with their name, record, label, and artwork, and every one of those names has to be right in front of an industry that knows them by name.
- 40Award categories
- 6–8Nominees per category
- 120+Finished rendersBlender and After Effects
- 2 hrsShow runtimeLive, immovable
The package used to take four months of full-time work. The 2026 show was the biggest yet and the time was a fraction of that, so I built the production as a system of agents to make a better show on a tighter timeline.
The system
Three specialists and a coordinator
Four agents. Three specialists, each running one application: Blender for nominee screens, After Effects for the 2D package, Premiere Pro for assembly. A coordinator held the source data and managed the handoffs between them.
The date was fixed and public. What they made is what aired.
The coordinator
What it actually held
Forty category titles. Three hundred nominee names, artwork, label credits, a reading order, and the render state of everything. Misspell one and it's a public failure in front of the person it belongs to.
One spreadsheet was the source of truth. The coordinator's whole job was making sure only that spreadsheet drove what each specialist produced.
The mechanism
Tool choice, and how the agent drives it
Nominee screens had lived in After Effects for years. They moved to Blender because of what each application lets an agent reach: After Effects exposes a narrow command surface, especially in 3D, while Blender exposes almost everything through Python. Once the operator is an agent, the size of that surface is a production constraint rather than a technical footnote. It outranks the tool a person would rather open.
The bridge itself is off the shelf: an add-on exposing Blender's Python API over a local socket, so an agent can query a scene and run scripts against it instead of clicking. What I wrote is the layer on top of it, a skill that tells the agent which commands Blender actually exposes instead of leaving it to guess. Guessing is where agents driving real applications fall over.
The production layer took the work. Blender runs headless, one file per category, launched --background --factory-startup from a queue. The agent writes Python against bpy, the queue executes it, and every run writes a log.
An agent operating a GUI application is easy to claim and hard to prove. The logs are the difference between saying this worked and showing it.
The verify gate
Forty-one seconds against fifty-three minutes
A full category render is about fifty-three minutes. A wrong one costs that, plus however long it takes somebody to notice, plus the re-render. So nothing reaches the queue until it passes a check.
The check renders one frame per nominee strip and scores it against the artwork that record is supposed to have. Under threshold, the file is skipped instead of queued. It takes about forty-one seconds.
Eight of twenty files failed and never rendered. Roughly seven hours of render that did not happen, bought for about five and a half minutes of checking.
# render_queue.live.log, first fourteen lines. Category paths shortened for display.
[22:58:54] VERIFY   Alternative-Rock-Record
[22:59:27]  PASS - rendering Alternative-Rock-Record
[23:45:11] RENDERED Alternative-Rock-Record  verify=33s render=2744s
[23:45:11] VERIFY   American-Roots-Record
[23:45:57]  FAIL - skipping full render of American-Roots-Record
[23:45:57] SKIPPED  American-Roots-Record    verify=46s render=0s
[23:45:57] VERIFY   Blues-Record
[23:46:31]  FAIL - skipping full render of Blues-Record
[23:46:31] SKIPPED  Blues-Record             verify=35s render=0s
[23:46:31] VERIFY   Classical-Record
[23:47:08]  PASS - rendering Classical-Record
[00:28:01] RENDERED Classical-Record         verify=36s render=2453s
[00:28:01] VERIFY   Country-Record
[00:28:37]  FAIL - skipping full render of Country-Record
What broke
The data, not the agents
The nominee reading order had to be alphabetical. It was about 85 percent alphabetical, with the exceptions in exactly the wrong places, and the system assumed 100. The order lived in three places at once: the source sheet, the voiceover script, and the animation. Nothing enforced agreement between them, so voiceover got recorded to one order, animation got built to another, and the timing came apart where they diverged.
Two things should have been true first: the voiceover recorded and confirmed in final order, and an automated check before anything reached the client. Instead, discrepancies a script could have caught surfaced in Frame.io review, about the most expensive place to catch them.
The smartest agents from the most advanced labs on earth cannot infer their way out of dirty data. "Mostly correct" in a system that needs exactness isn't a rounding error, it's a defect. Most writing on this treats the agents as the interesting part. Here they did their job. The failure was upstream of them.